Why is Your IT Team Always Putting Out Fires?
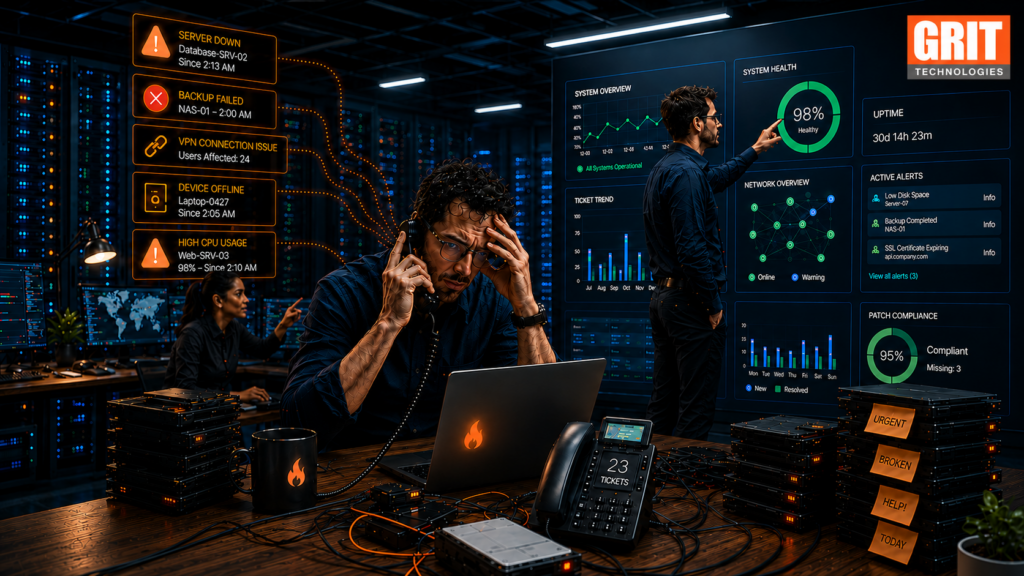
Your IT team didn’t sign up to be firefighters. They were hired to build systems that make the business productive, safer, and more competitive. Yet most days they open the ticket queue and spend the next eight hours chasing the latest outage, password reset, or “why is the printer broken again?” request.
The result is predictable: strategic projects stall, innovation slows, and the talented professionals who should be driving technology forward end up stuck reacting to constant fires. Over time, that same talent often becomes frustrated, burned out, or quietly looking for their next opportunity.
Why reactive mode becomes the default
Internal IT teams rarely choose this cycle. It chooses them. Common triggers include:
- Ticket volume that never stops growing. Every new employee, application, and device adds demand. Without enough capacity, the team stays locked in break-fix mode.
- Aging systems that break more than they should. Outdated infrastructure, unpatched servers, and unsupported software create a steady stream of preventable emergencies.
- No early-warning system. When monitoring is weak or nonexistent, small issues quickly escalate into bigger problems that cost far more time and money to fix.
- Missing specialized skills. Cloud architecture, cybersecurity, and modern networking require expertise a lean internal team often can’t fully implement or maintain.
- A culture that rewards speed over root cause. When success is measured by how fast tickets close instead of how many problems are prevented, firefighting becomes the norm.
The warning signs leaders often miss
You don’t need a dashboard full of red lights to know something is wrong. Here are some common warning signs to watch for:
- The same issues keep reappearing every few weeks.
- Major projects (cloud migration, security upgrades, system refreshes) sit on the shelf for months with little progress.
- Far too often, your best IT people are working nights and weekends.
- Employees start building their own shadow IT because “IT is too busy.”
- Growth plans are delayed or scaled back because “the systems aren’t ready.”
These aren’t just operational annoyances. They’re early indicators that your technology has shifted from competitive advantage to constraint.
Six questions every operations leader should ask right now
Use these questions as a practical evaluation checklist:
- What percentage of our IT team’s time is spent on reactive support versus proactive improvement?Why it matters: This reveals whether capacity is being consumed by firefighting or invested in progress.
Strong answer: “We track this monthly. Currently reactive work is under 40%, leaving the team dedicated time for roadmap projects.”
Red flag: “Almost everything is reactive—we’re just trying to keep up with tickets.” - Which recurring problems have we known about for more than six months and are still not permanently fixed?Why it matters: Long-standing issues signal missing root-cause analysis or insufficient resources.
Strong answer: “We maintain a prioritized list of chronic issues and have resolved or scheduled permanent fixes for all of them within the last two quarters.”
Red flag: “We’ve learned to live with a few of them.” - Do we have an actual technology roadmap that is reviewed and funded alongside the business plan?Why it matters: Without a living roadmap, IT stays tactical instead of strategic.
Strong answer: “Yes. We review and update it quarterly with leadership and align budget to the highest-impact initiatives.”
Red flag: “We have a list of projects, but it isn’t formally reviewed or funded with the business plan.” - If our IT team suddenly had 25–30% more capacity and specialized expertise, what strategic initiatives would finally move forward?Why it matters: This surfaces the opportunity cost of the current model.
Strong answer: “We already know exactly which security, cloud, and automation projects would accelerate once capacity is available.”
Red flag: “We’re not sure—we’re too buried in day-to-day work to think that far ahead.” - Who is responsible—day and night—for spotting and preventing issues before they disrupt the business?Why it matters: Clear ownership of prevention is what separates proactive from reactive operations.
Strong answer: “We have continuous monitoring and defined escalation paths so potential problems are addressed before users notice them.”
Red flag: “We usually find out when something breaks or when a user reports it.” - Are we measuring IT success by how many fires they put out, or by how few fires occur?Why it matters: Metrics drive behavior. Ticket volume alone encourages more firefighting.
Strong answer: “We measure reduction in unplanned downtime, mean time to resolution trends, and progress against the technology roadmap.”
Red flag: “We mainly track how many tickets get closed each month.”
- What percentage of our IT team’s time is spent on reactive support versus proactive improvement?
Honest answers to these questions usually reveal the same truth: the current model isn’t sustainable if the business intends to grow.
The shift from firefighter to strategist
A proactive approach changes the math. Continuous monitoring, automated patching, regular health checks, and a clear roadmap dramatically reduce urgent tickets. With fewer emergencies demanding attention, your internal team finally gains bandwidth for higher-value work that drives real growth.
This is where the right external partnership becomes transformative. Managed or co-managed IT support expands your team’s expertise and capacity — without the overhead of additional headcount. Day-to-day support operations and incident prevention are handled proactively, freeing your people to focus on what matters most.
| Traditional Reactive Approach | Proactive Technology Partnership | |
|---|---|---|
|
Responds after something breaks
|
Continuously monitors systems and resolves issues before they disrupt operations |
|
|
Focuses on closing tickets quickly
|
Focuses on preventing problems and improving long-term performance |
|
|
Treats each incident in isolation |
Identifies patterns and eliminates root causes |
|
|
Limited specialized expertise in-house
|
Brings deep expertise in cloud, security, and modern infrastructure |
|
|
Success measured by tickets resolved |
Success measured by reduced downtime, stronger security, and strategic progress |
|
|
Internal team stays buried in day-to-day support |
Internal team gains capacity for high-value projects that drive growth
|
|
Where GRIT fits
If the queue is full and the projects that would shrink it never get a clean week, the team isn’t the problem. The week is.
GRIT Technologies gives growing companies extra capacity through managed or co-managed IT: monitoring, patching, day-to-day support, and skills a lean team usually can’t keep on staff. The aim is straightforward. Take the preventable work off your people so the stuck projects can move.
The fires will keep coming until someone changes the system that creates them. Contact GRIT and we’ll look at what’s filling the week.
Frequently Asked Questions
Why do internal IT teams get stuck in reactive mode?
Usually because the work keeps growing and the team doesn’t. New people, new apps, and aging systems add tickets. Without enough capacity, monitoring, or time to fix the root cause, the ticket queue wins and the roadmap waits.
What are the biggest warning signs that your IT operation is too reactive?
The same issues keep coming back. Big projects sit for months. Your best people are working nights and weekends. Staff start finding their own workarounds because IT is too busy. Growth plans get delayed because “the systems aren’t ready.”
How can a proactive approach free up my team’s time?
When monitoring, patching, and routine fixes happen before users notice, urgent tickets drop. That doesn’t magically create a new person. It gives the people you already have room to work on the projects that were stuck.
What’s the difference between managed and co-managed IT?
Managed IT takes on day-to-day support and prevention. Co-managed IT works alongside your team and fills in the gaps — extra hands, after-hours coverage, or skills you don’t want to hire for. Neither one has to replace your people.
How soon can we expect results?
Some of the noise usually quiets down in the first month or two: fewer repeat issues, clearer ownership, a restore or a monitoring gap you can actually point to. The bigger shift — a team that isn’t buried in break-fix — takes longer than a quick win.